The sampling problem
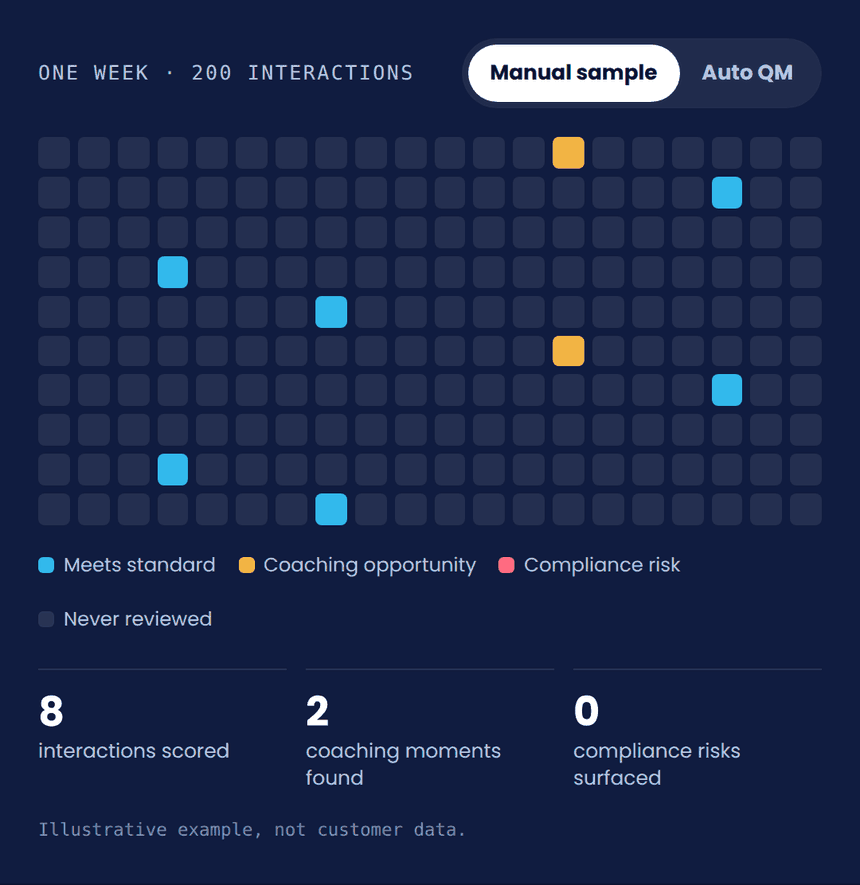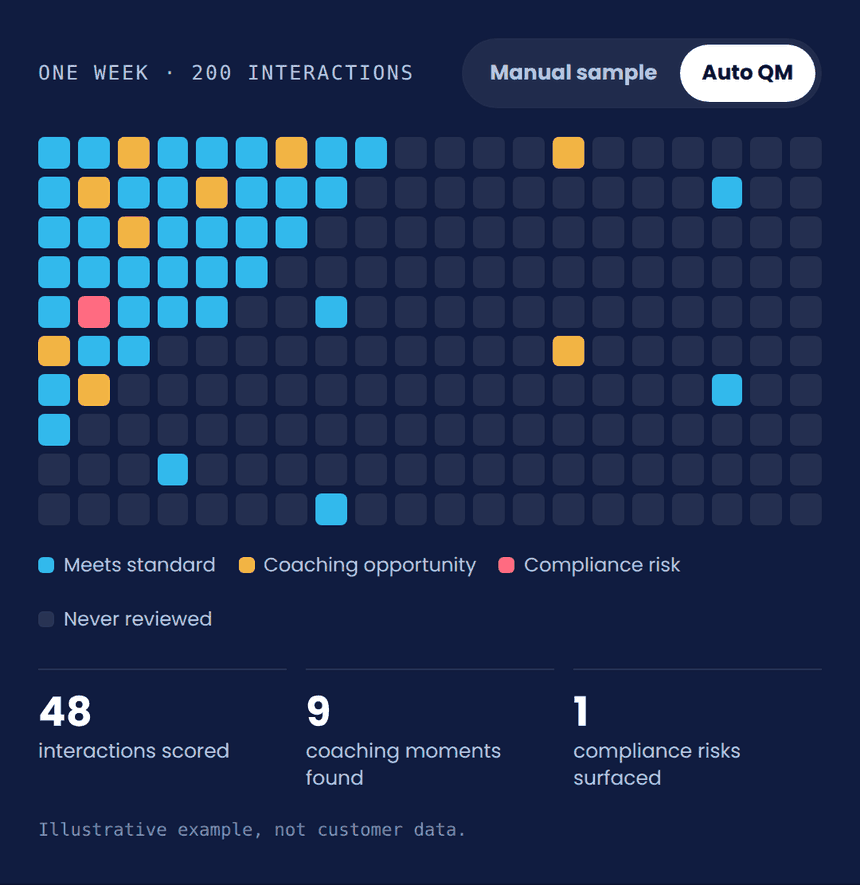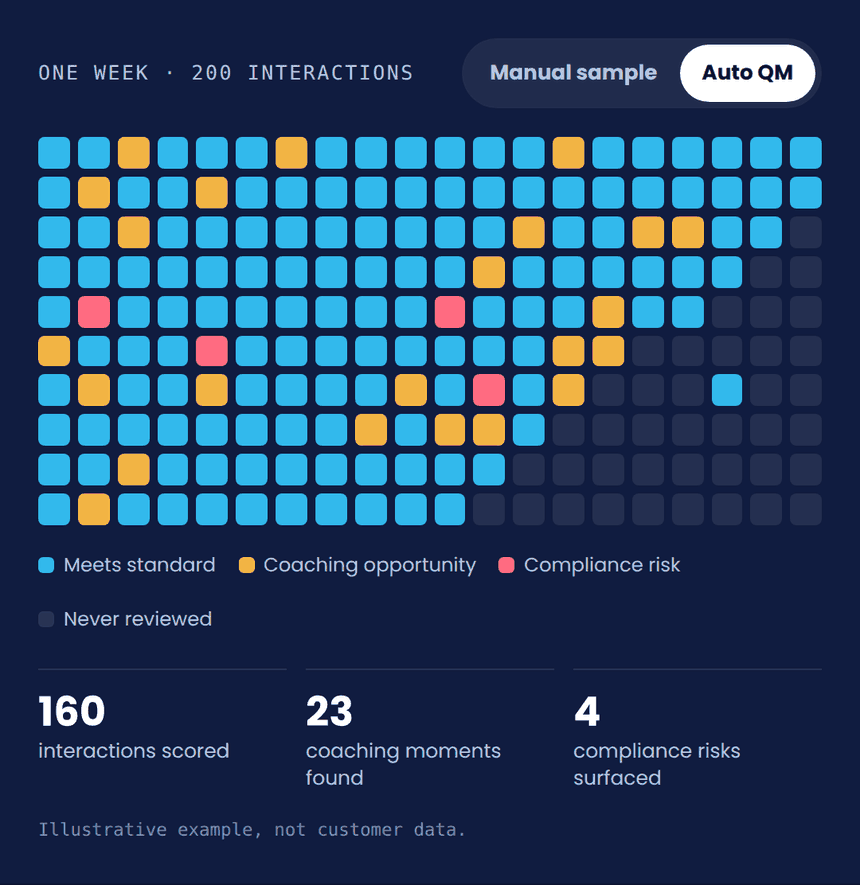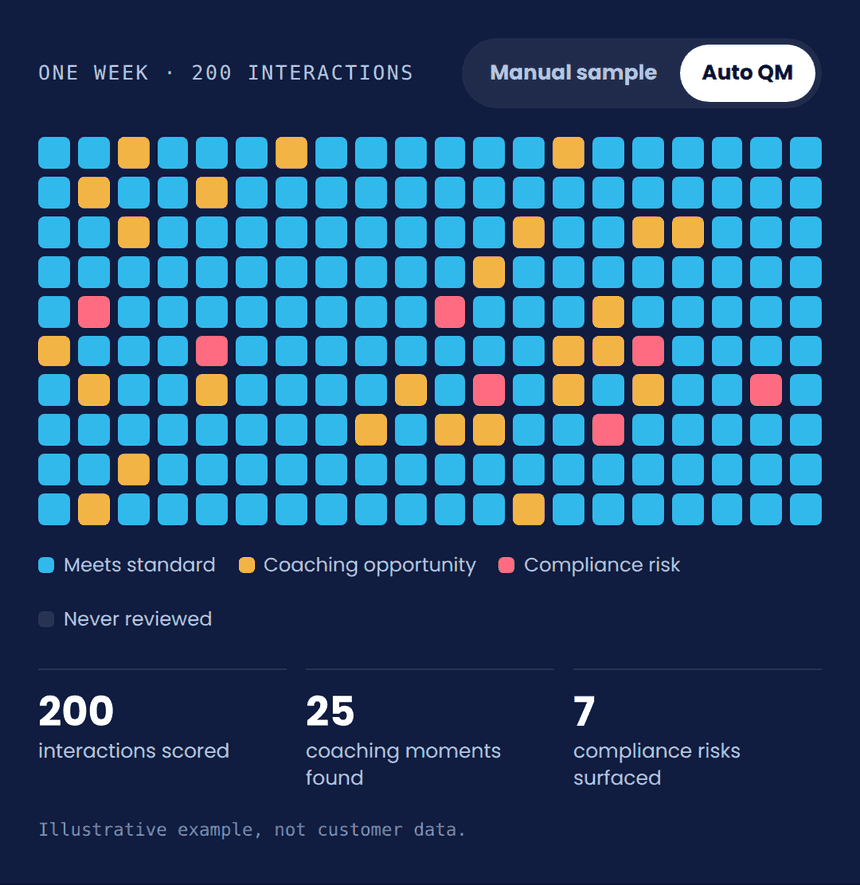
Manual review means a few calls per agent per month, picked mostly at random. Everything else goes unheard, and the risk, the coaching opportunities and what customers are telling you go with it.
Risk
A missed disclosure or a skipped verification step only shows up in QA if that exact call happened to be sampled. At scale, that isn’t an assurance program. It’s luck.
Coaching
When an agent has three evaluations a month, one bad call can define their review. Supervisors can’t tell a habit from a one-off, and agents feel it.
Customer
Why are people calling back? What’s driving cancellations? The answers are already in your recordings, in the calls nobody has time to review.
Auto QM changes the question from “what did we happen to review?” to “what actually happened?”
Turn on GenAI Scoring for any evaluation form you already use. SuccessKPI scores each question the way your best evaluator would: against your policies, grounded in real call data, and with the evidence shown.
Enable AI on existing or new evaluation forms with one toggle. Target exactly which interactions get scored by queue, talk time, media type, DNIS or call direction, so the AI focuses where it counts.
Add up to three guidance prompts per question. For “Did the agent greet the customer properly?”, a prompt like “Did the agent introduce themselves?” tells the AI exactly what to look for.
Some questions can’t be answered from a transcript alone. With Metrics enabled, the AI reads hold time, wait time, talk time, ACW, handle time and transfers from the call record. “Put on hold for more than 30 seconds?” gets scored on what the system logged, not on what the agent said.
Link a question to your knowledge base (SOPs, product manuals, compliance scripts) and the AI checks the transcript against the right passages. Asked whether an agent followed the five-step account-closure verification, it compares the call to your procedure, not a generic idea of good service.
Run any question against a real conversation ID before it goes live. See the answer, the reasoning and the confidence, then refine the prompt until it scores the way your team would.
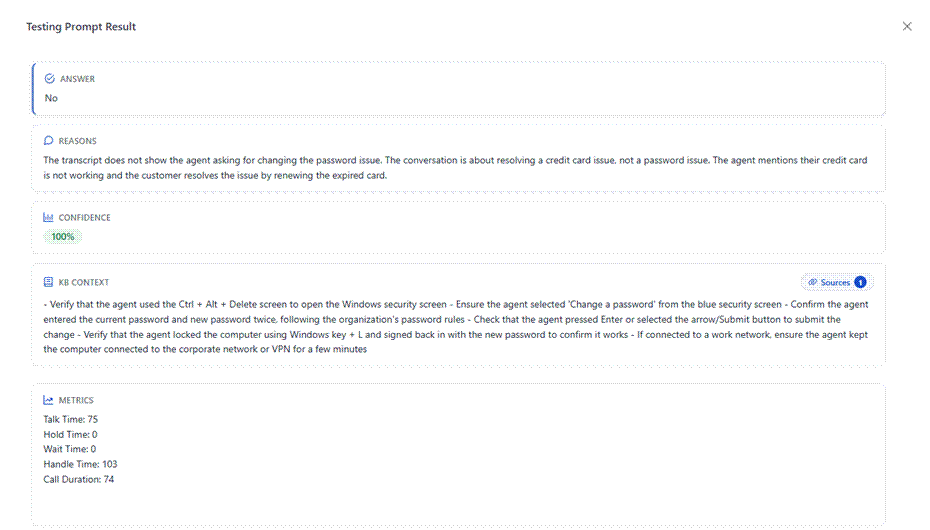
Every AI answer shows its work: the reasons, a confidence score, the knowledge base passages it relied on, and the call metrics it read.
Yes / No / N/A or scaled
Scored against your form’s own scale and weighting.
Plain-language rationale
Why the AI answered that way, tied to the conversation.
How sure it is
So evaluators know which answers to double-check.
Policy evidence
The source passages used, with a link back to the article.
System facts
Hold, wait, talk and handle time read from the call record.
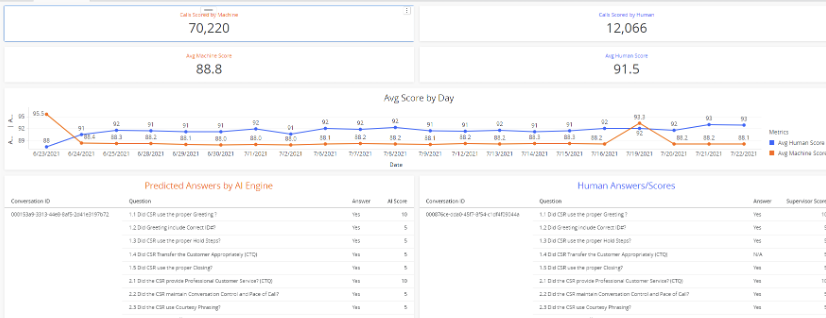
Adopting AI scoring shouldn't mean taking it on faith. SuccessKPI puts AI results next to your evaluators' scores in the Reports Library, question by question, so you can see where they agree, find where they don't, and tune the guidance until the numbers track. Calibration sessions, evaluator Co-Pilot suggestions and a full dispute workflow keep people in charge of the standard, while AI does the volume.
What 100% coverage unlocks
When every conversation is scored, quality stops being a sample-based report card and becomes an operating signal for the whole business.
Compliance & risk
Disclosures, verification steps and script adherence are checked on every call in scope, not only the ones someone happened to pick.
Supervisors
See an agent’s trends across all of their interactions, then spend coaching time on the habits that move results.
Agents
Every agent is measured the same way on the full body of their work, with reasons they can read and dispute.
QA teams
Hours spent listening to routine calls go to calibration, root cause and the conversations that need human judgment.
CX leaders
Tie quality to resolution, effort and sentiment to see which issues, queues and handoffs are costing you loyalty.
Executives
Link quality to first-contact resolution, repeat contacts, retention and cost to serve, and report it with confidence.
Customer results
Insurance · 400+ agents · 75,000 calls a month
“SuccessKPI GenAI enabled us to discover what traditional quality monitoring could never reveal. By identifying our highest-performing retention behaviors and transforming those insights into a specialized operation, we dramatically improved customer retention and protected significant business revenue in only two months.”
Celso Roberto Teixeira, Quality Manager, MAPFRE
Retention rate on cancellation calls
Revenue protected (about USD 200K)
Scored by AI with human review, up from a manual sample
Human + AI CX
Your AI agents are already talking to customers. SuccessKPI treats an AI agent conversation as just another interaction: it’s scored on the same form, to the same standard, in the same reports as your human agents. So you can finally answer the question that matters: who handles this intent better?
A contained call isn’t a resolved call. SuccessKPI measures outcomes with the CARES framework, including whether the customer came back within 72 hours with the same problem.
Compliance
Stayed within scope and policy
Accuracy
Right answer, right action, right escalation
Resolution
A durable fix that passes the 72-hour test
Effort
How hard the customer had to work
Sentiment
How they felt across the journey
Across dozens of sites, several regions and thousands of calls a day, finding the conversations that matter most shouldn’t take an afternoon of filtering. With Smart Selections, supervisors ask in plain English and get the right interactions back in seconds, each with the AI’s reasoning.
Search your whole interaction history with natural language, or start from presets for compliance risk, customer frustration, first-call-resolution gaps, training gaps and escalations. Write custom prompts for your own programs.
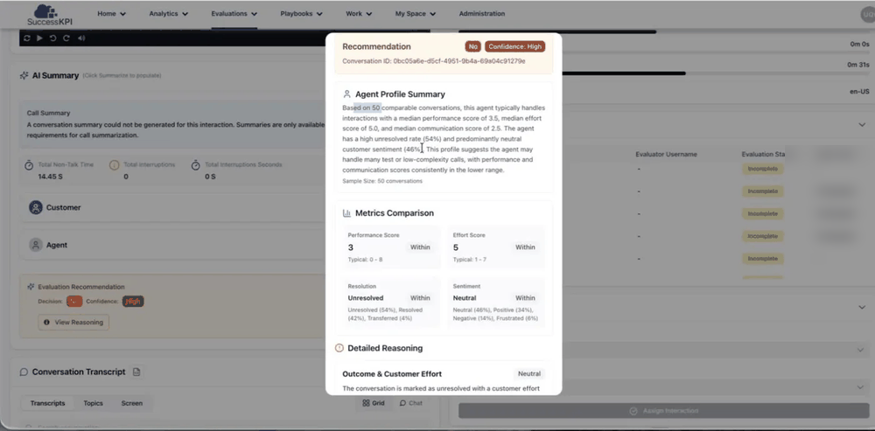
Skip the 30-minute listen-through. Get a contact summary, sentiment for agent and customer, interruptions and non-talk time, plus a draft evaluation with coaching recommendations compared against the agent’s own history.
Illustrative results. Conversation IDs and reasoning are examples.
AI surfaces the candidates and drafts the analysis. Your evaluators still read the reasoning, make the call and own the coaching conversation. Think of it as a second opinion your team can trust, question or overrule.
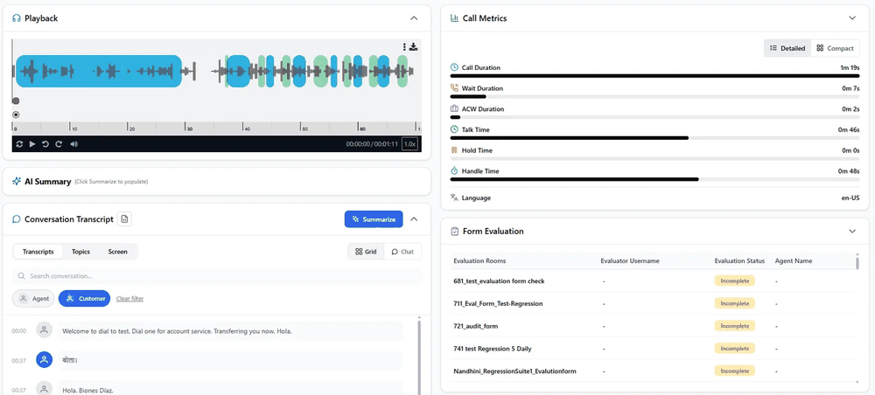
The complete QM workflow
Auto QM is the engine. The rest of the program is here too, so insights turn into coaching and coaching turns into results.
Build
Describe the form you need and AI Mode drafts the questions and categories in seconds. Refine by prompt or by hand.
Select
Route interactions in automatically with Playbooks and call hydration, or find them with Smart Selections.
Score
GenAI Scoring evaluates at scale. Evaluation Co-Pilot suggests answers and reasoning to human evaluators.
Calibrate
Keep humans and AI aligned with calibration forms, side-by-side reports and moderated disputes.
Coach
Launch coaching sessions from evaluations, schedule around the agent’s shift, and let agents track progress in My Space.
Most quality tools were built as part of a phone system, a workforce suite or a speech analytics engine, and AI was added later. SuccessKPI was built to measure performance across every channel, every platform and now every kind of agent.
We don’t sell a CCaaS platform or an AI agent, so nothing we score is ours. You get an objective view across every vendor in your stack.
Human agents, AI agents and the handoffs between them, scored on the same form with CARES outcome measures.
Reasons, confidence, knowledge base sources and system metrics come with every AI answer. No black-box numbers.
Switch AI on for the evaluation forms you already use, grounded in your SOPs. No need to rebuild your program around a vendor’s template.
Test prompts on real conversations before going live. GenAI Scoring doesn’t require months of labeled training data first.
Quality connects to Playbooks, real-time assist, BI and workforce management, so a finding turns into action without another tool.
| If you’re evaluating | How they approach quality management | The SuccessKPI advantage |
|---|---|---|
| GenesysCCaaS-native QM | QM and AI agents built for the Genesys platform | Independence. We score every interaction and provide third-party scoring of AI agents. |
| Amazon ConnectHyperscaler, native analytics | Contact Lens analytics built for the Connect platform. | One scorecard. Every platform, channel, and vendor in your stack. |
| CallMinerConversation analytics | Speech and text analytics, with QM on the analytics engine. | The full quality loop. Scoring, calibration, coaching, and action together. |
| Level AIAI-native auto-QA | Auto-QA scored on its own AI models. | Explainable scoring. Audit-ready results you can defend to a regulator. |
| AmplifAIPerformance enablement | Reads QA data from other systems to drive coaching. | The system of record. We capture and score quality, not read it. |
Buyer's checklist
Look for reasons, confidence and sources on every answer.
If not, you’ll have two standards and no comparison.
Hold time and transfers aren’t always said out loud.
Generic “good service” isn’t your compliance standard.
Tuning on real calls beats discovering drift in production.
Independence matters when the results go to the board.
Pick a high-volume queue and your current evaluation form. We’ll show you what Auto QM finds when every conversation is scored, human and AI alike.
Automated QA scores the questions you configure on every call and shows its reasoning. See how to set it up and check whether coaching worked.
Watch now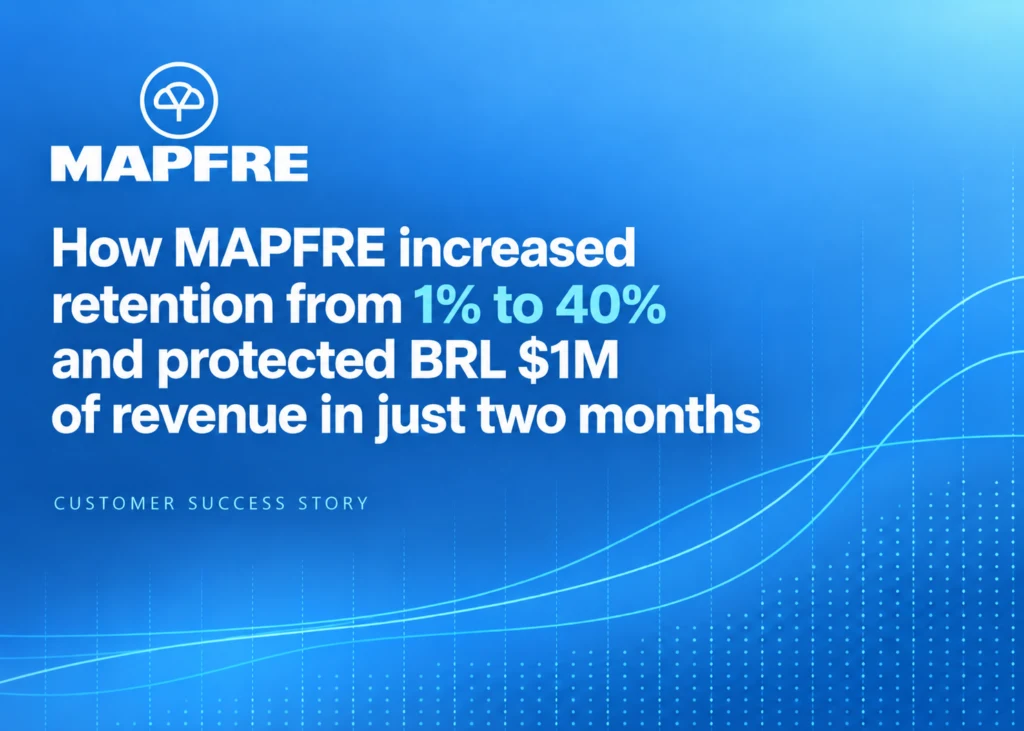
Learn how insurance giant identified revenue loss and mobilized their best agents to retain customers.
Read the case study
AI plans and strategy are ready. Execution is elusive. We asked 400 global contact center leaders about the tools they use and the tools they give their agents, then scored transformation maturity across seven pillars.
Get the report